Do blind battles reveal any bias?
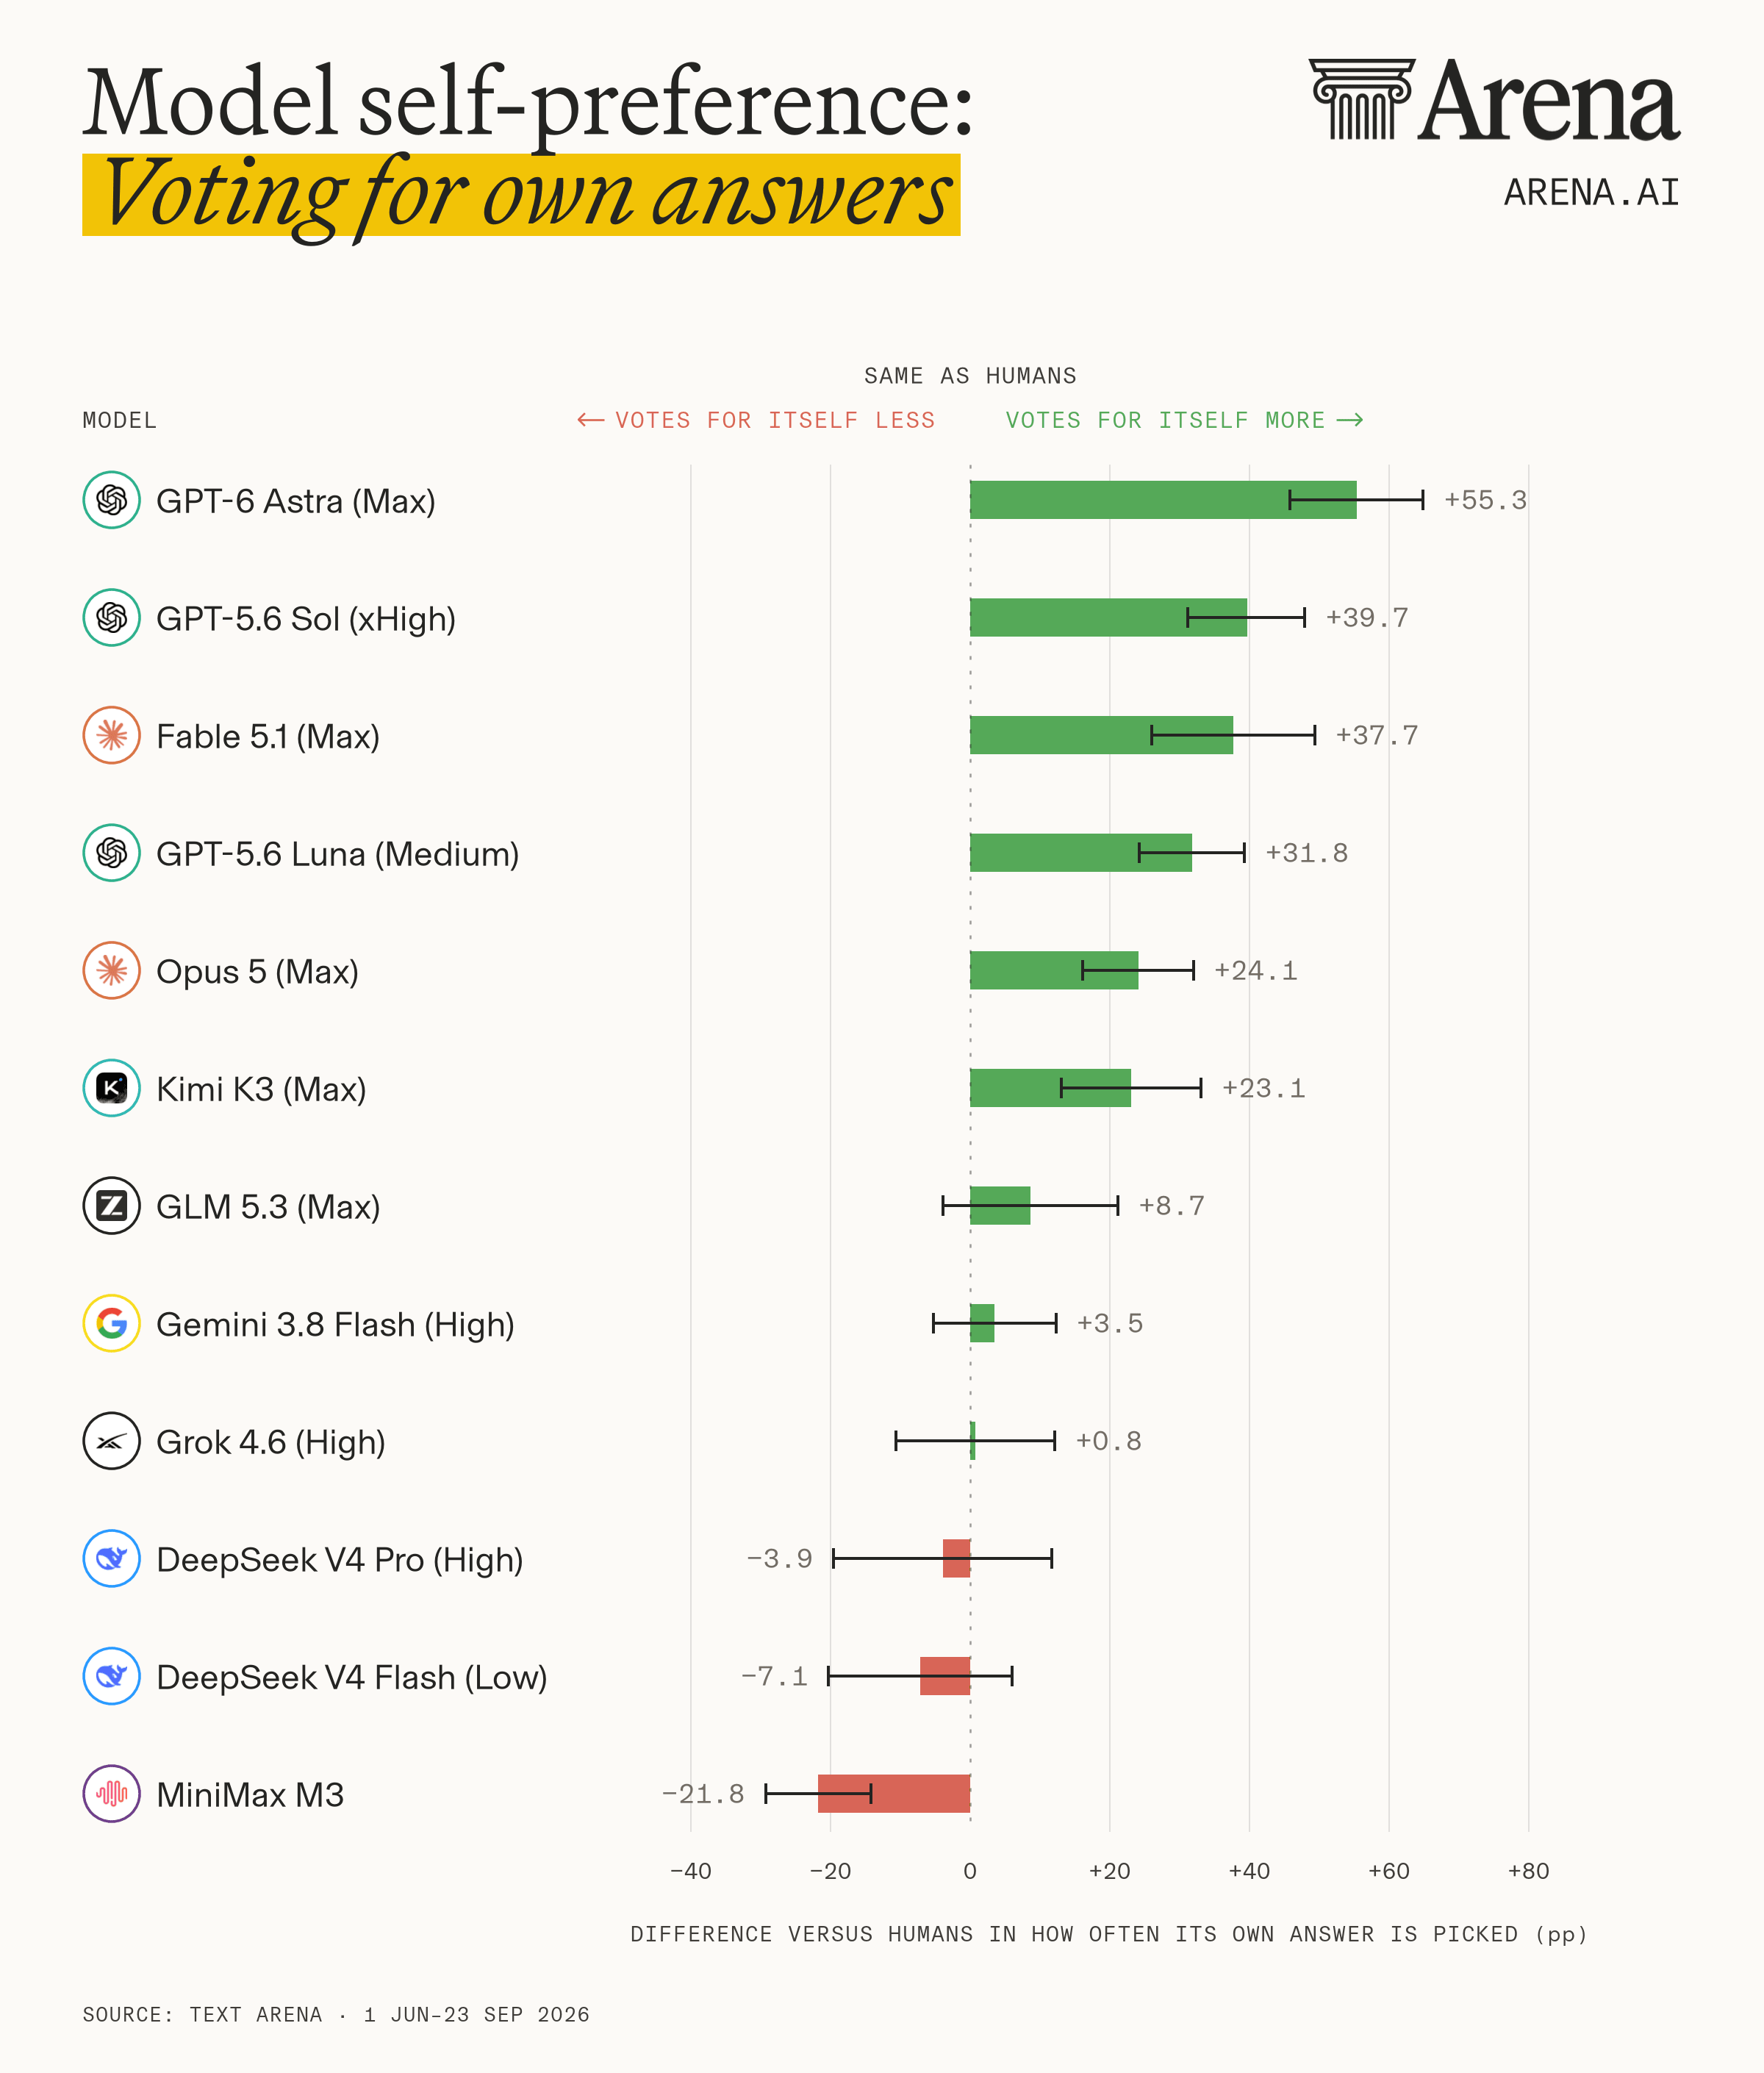
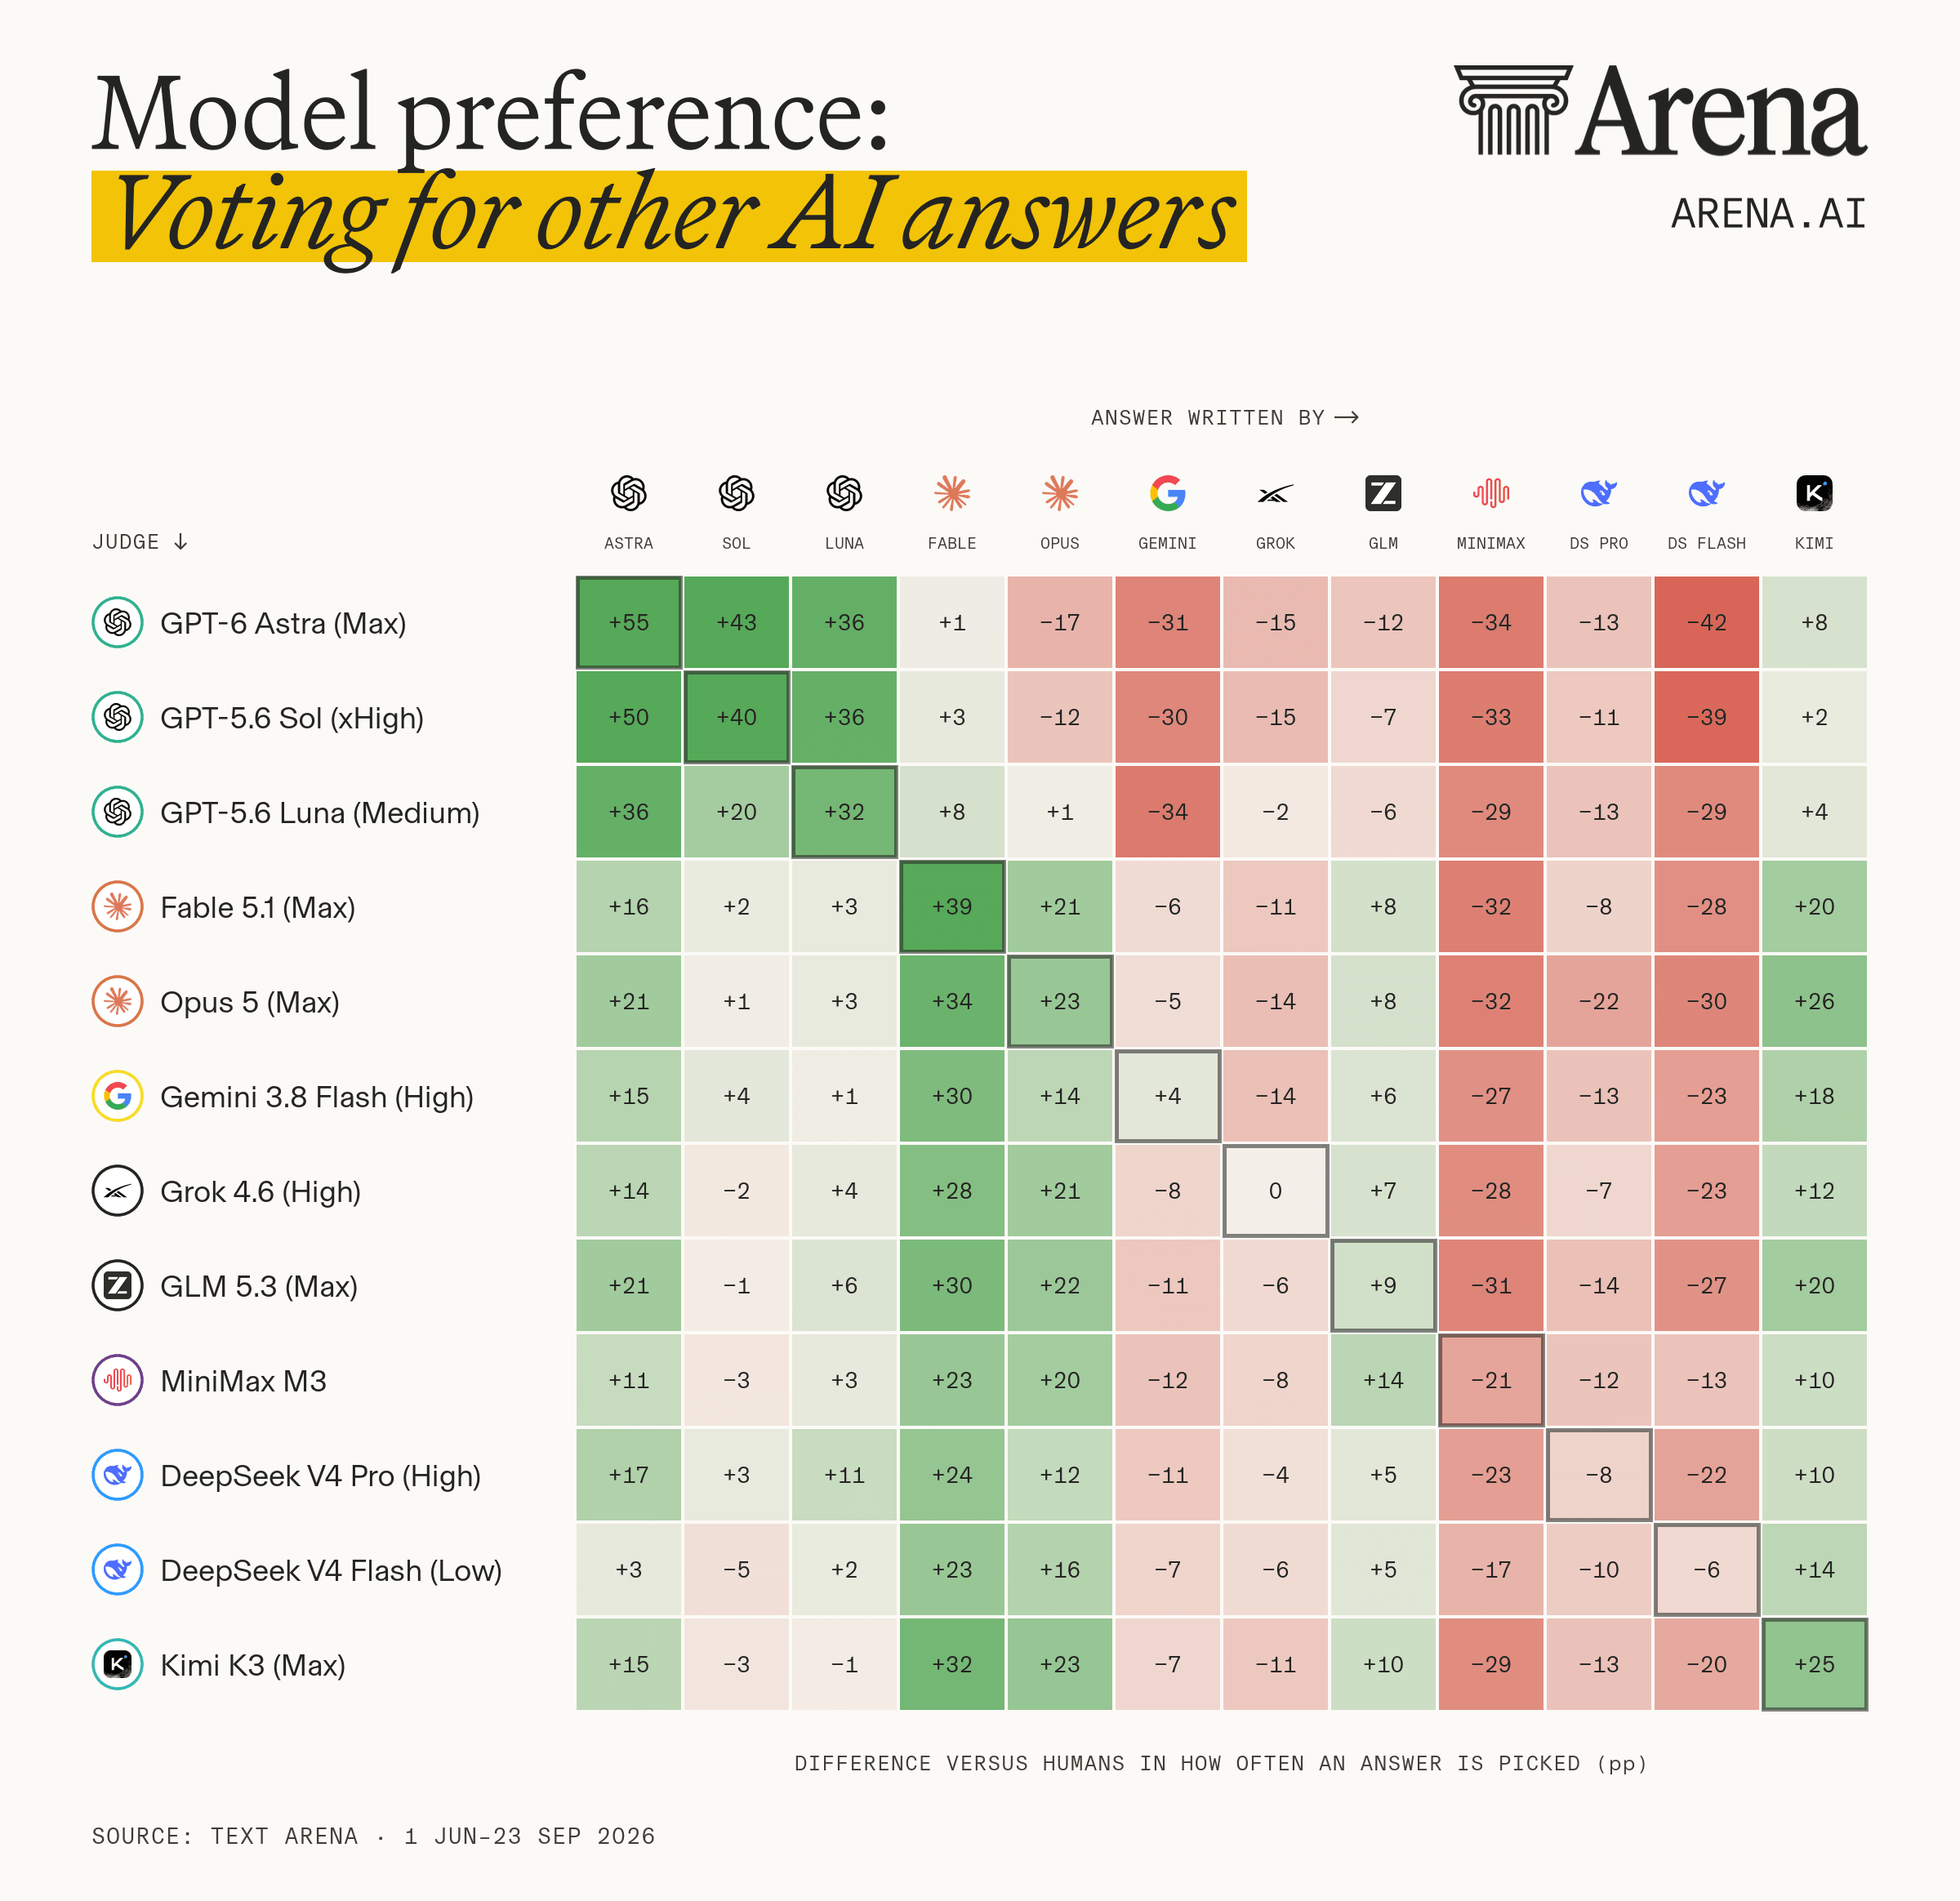
Astra picked itself in 88% of its battles, Fable in 72%.
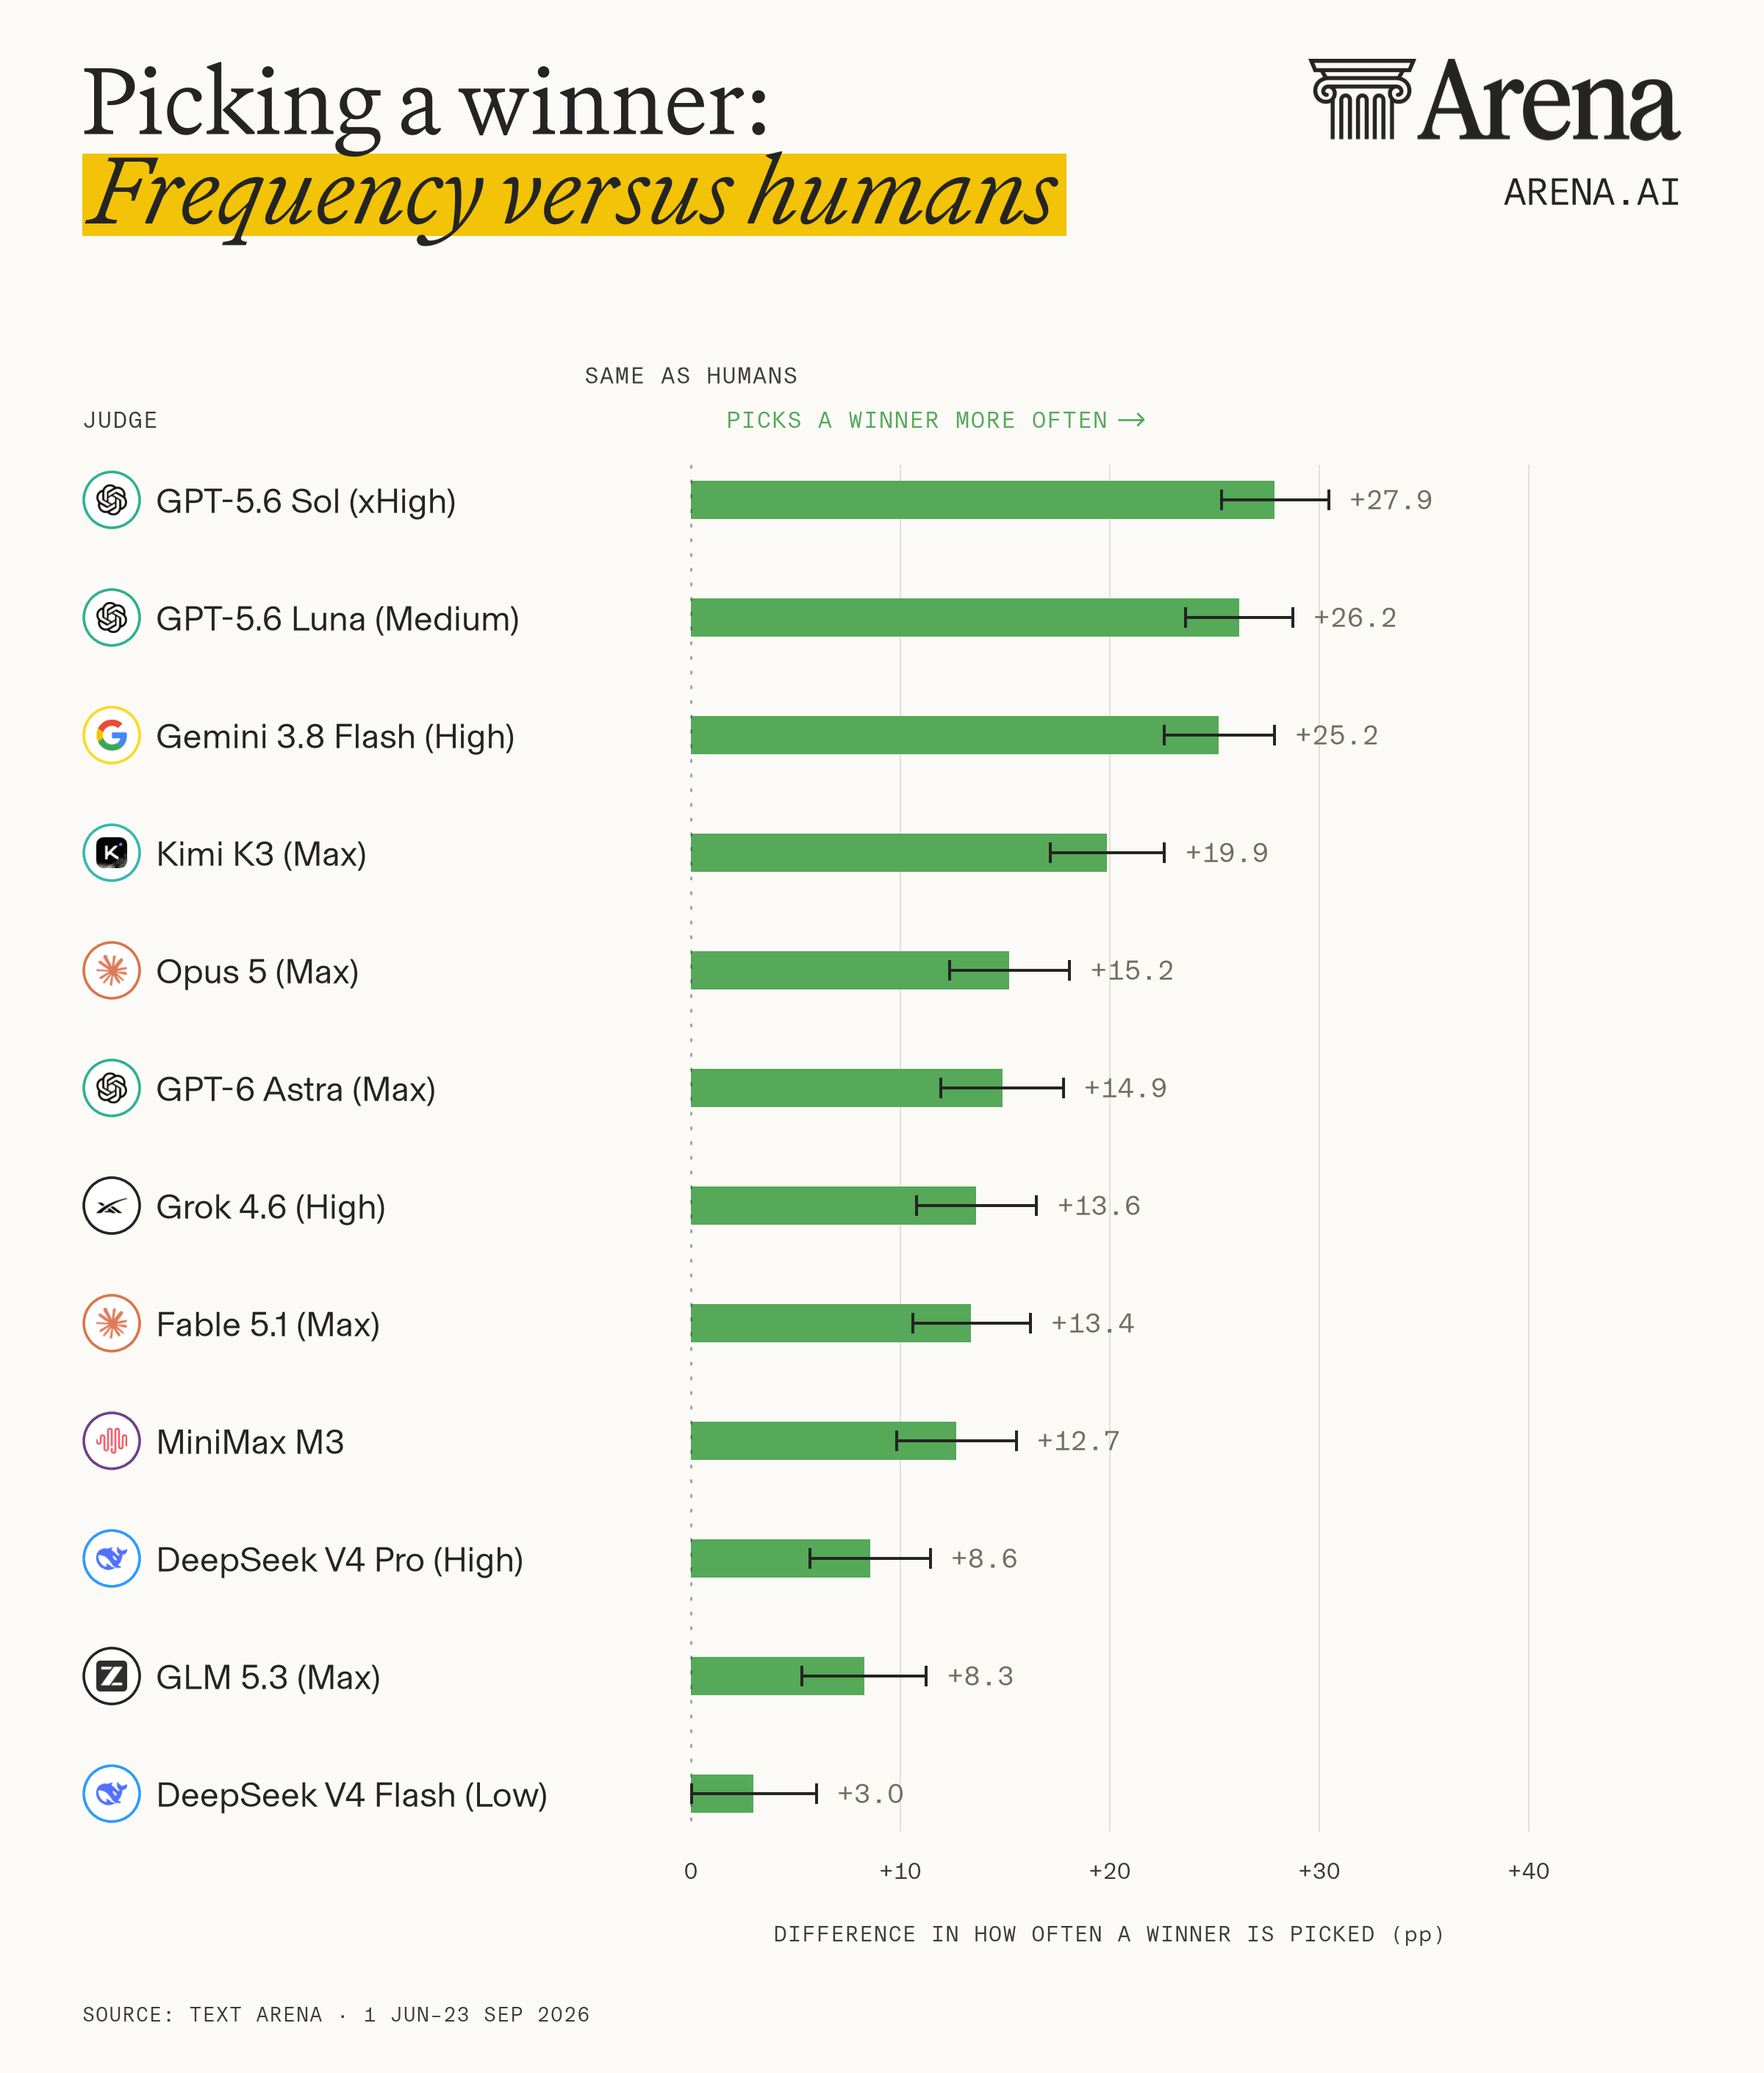
When Arena users enter Battle Mode, their prompt goes to two randomly selected models. They then pick the better answer, call a tie, or say both are bad. We gave the same task to AI judges, without telling them which models wrote the answers.
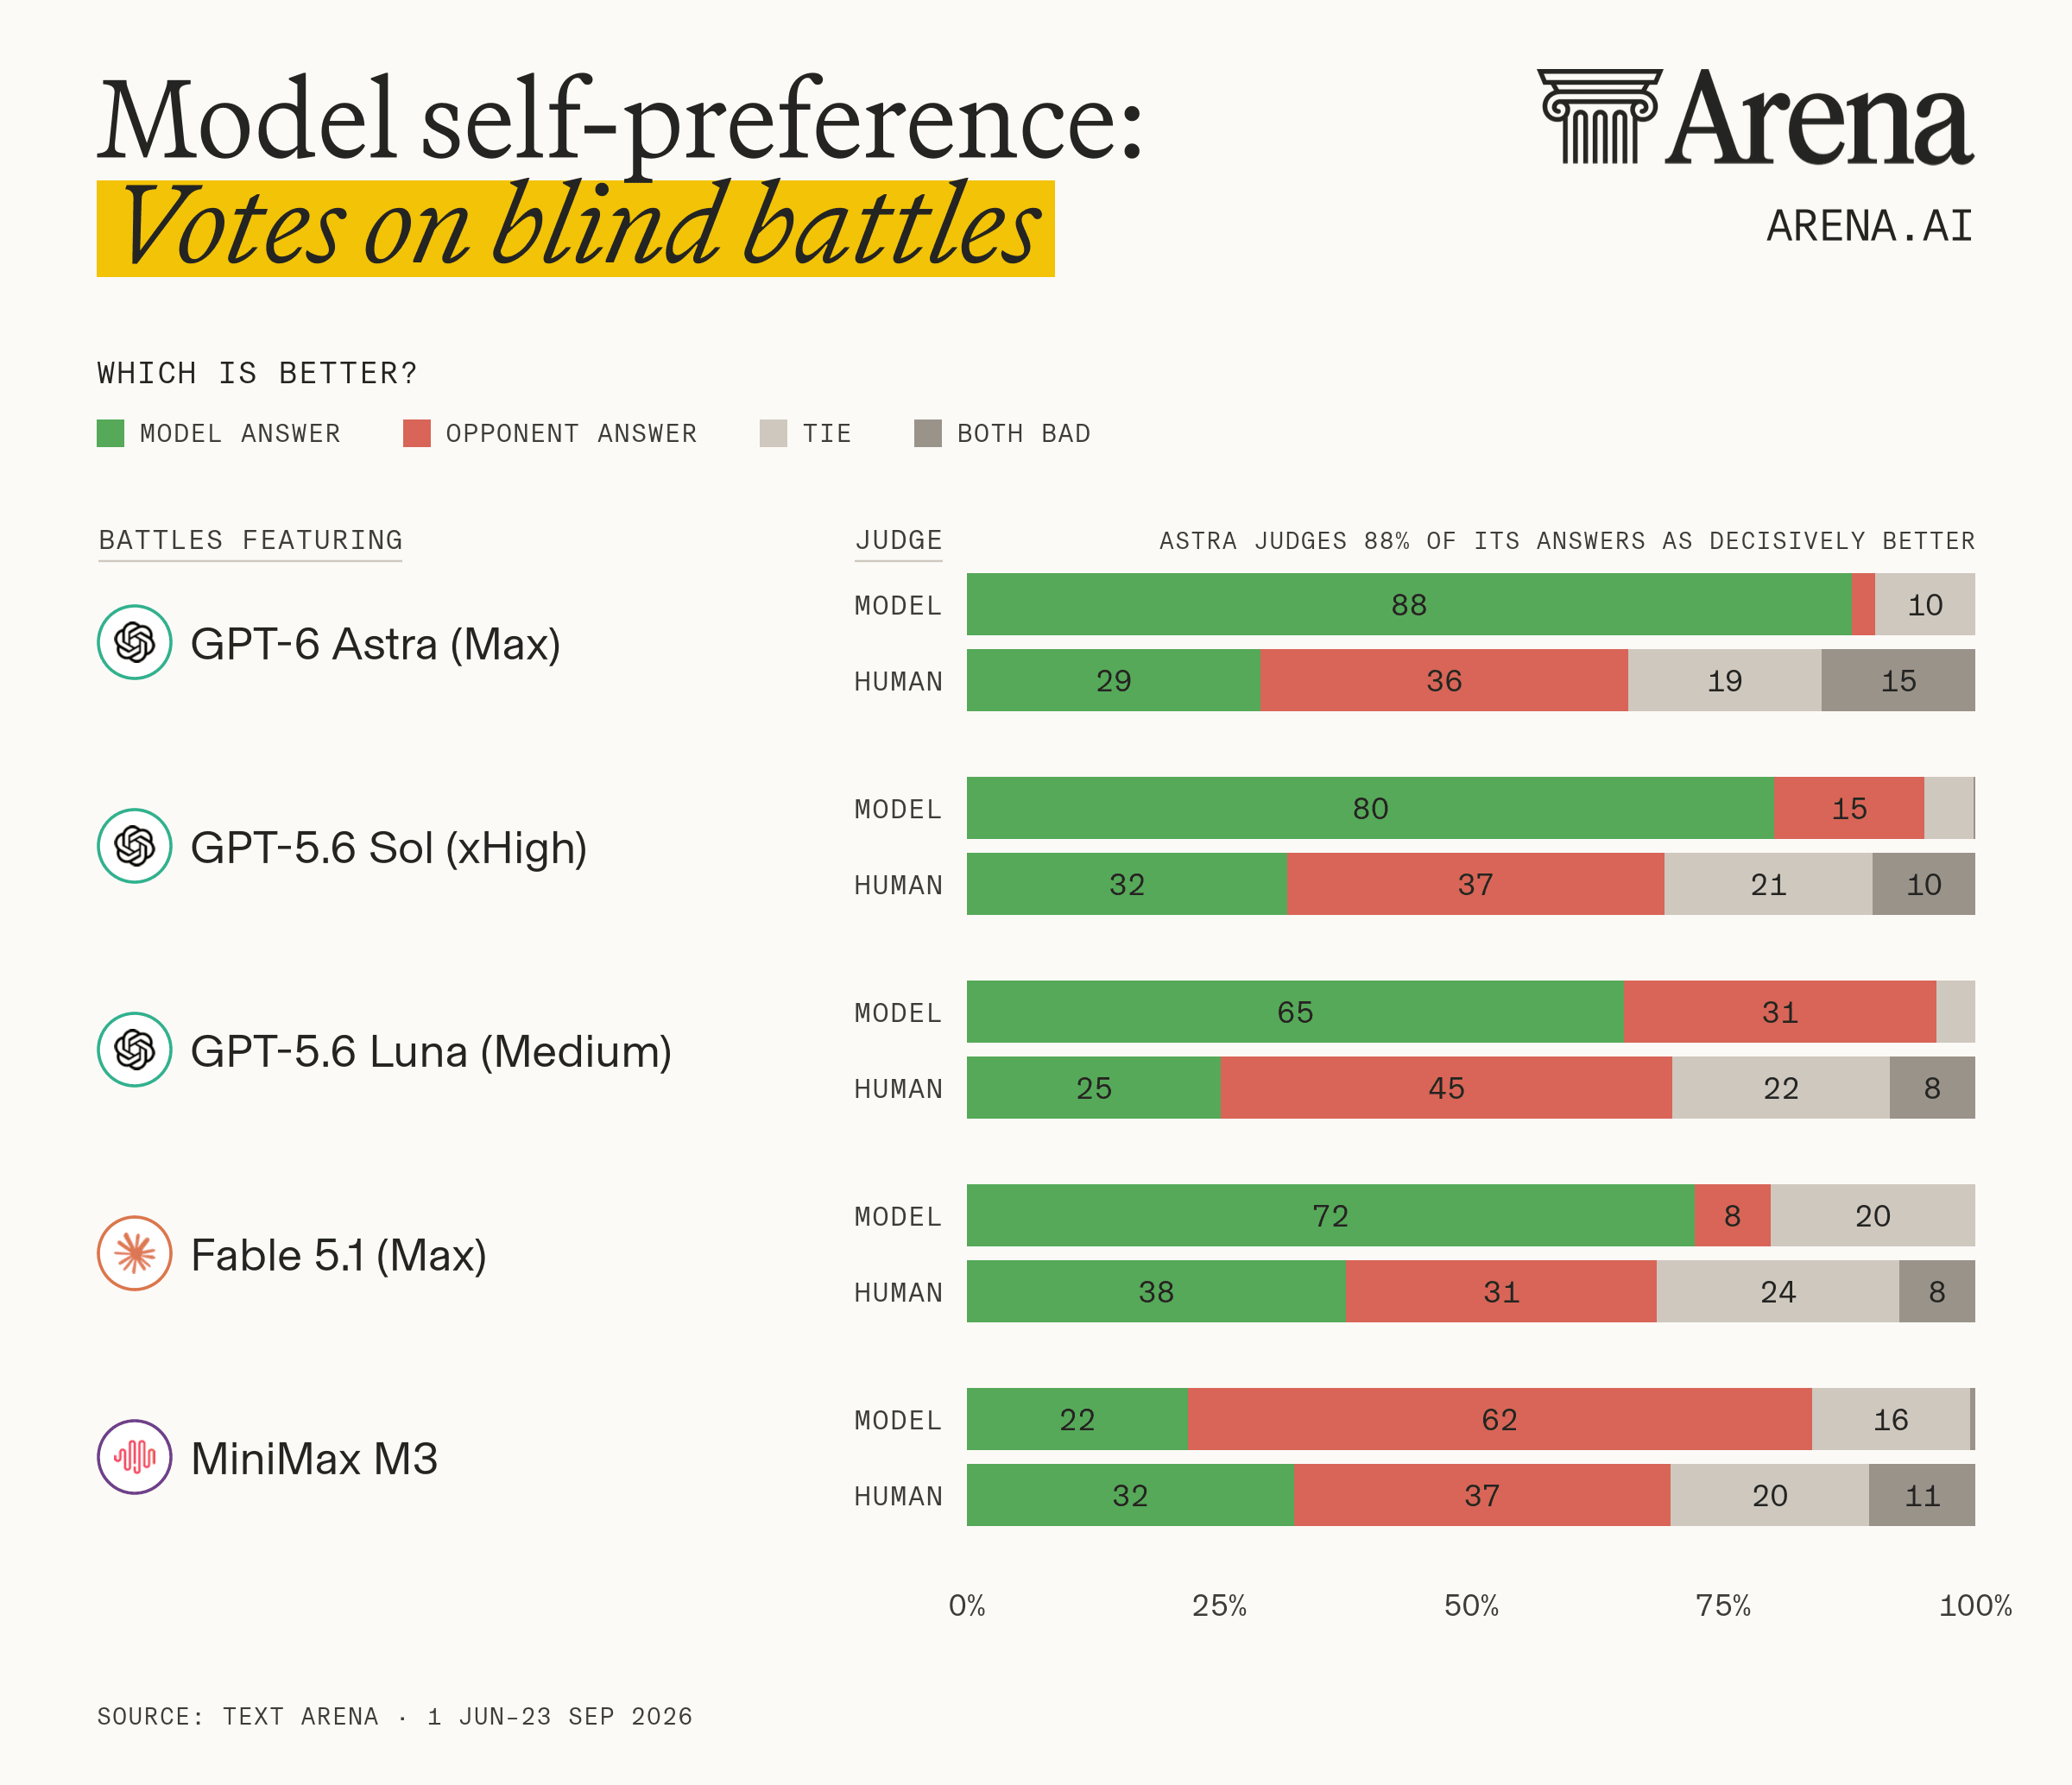
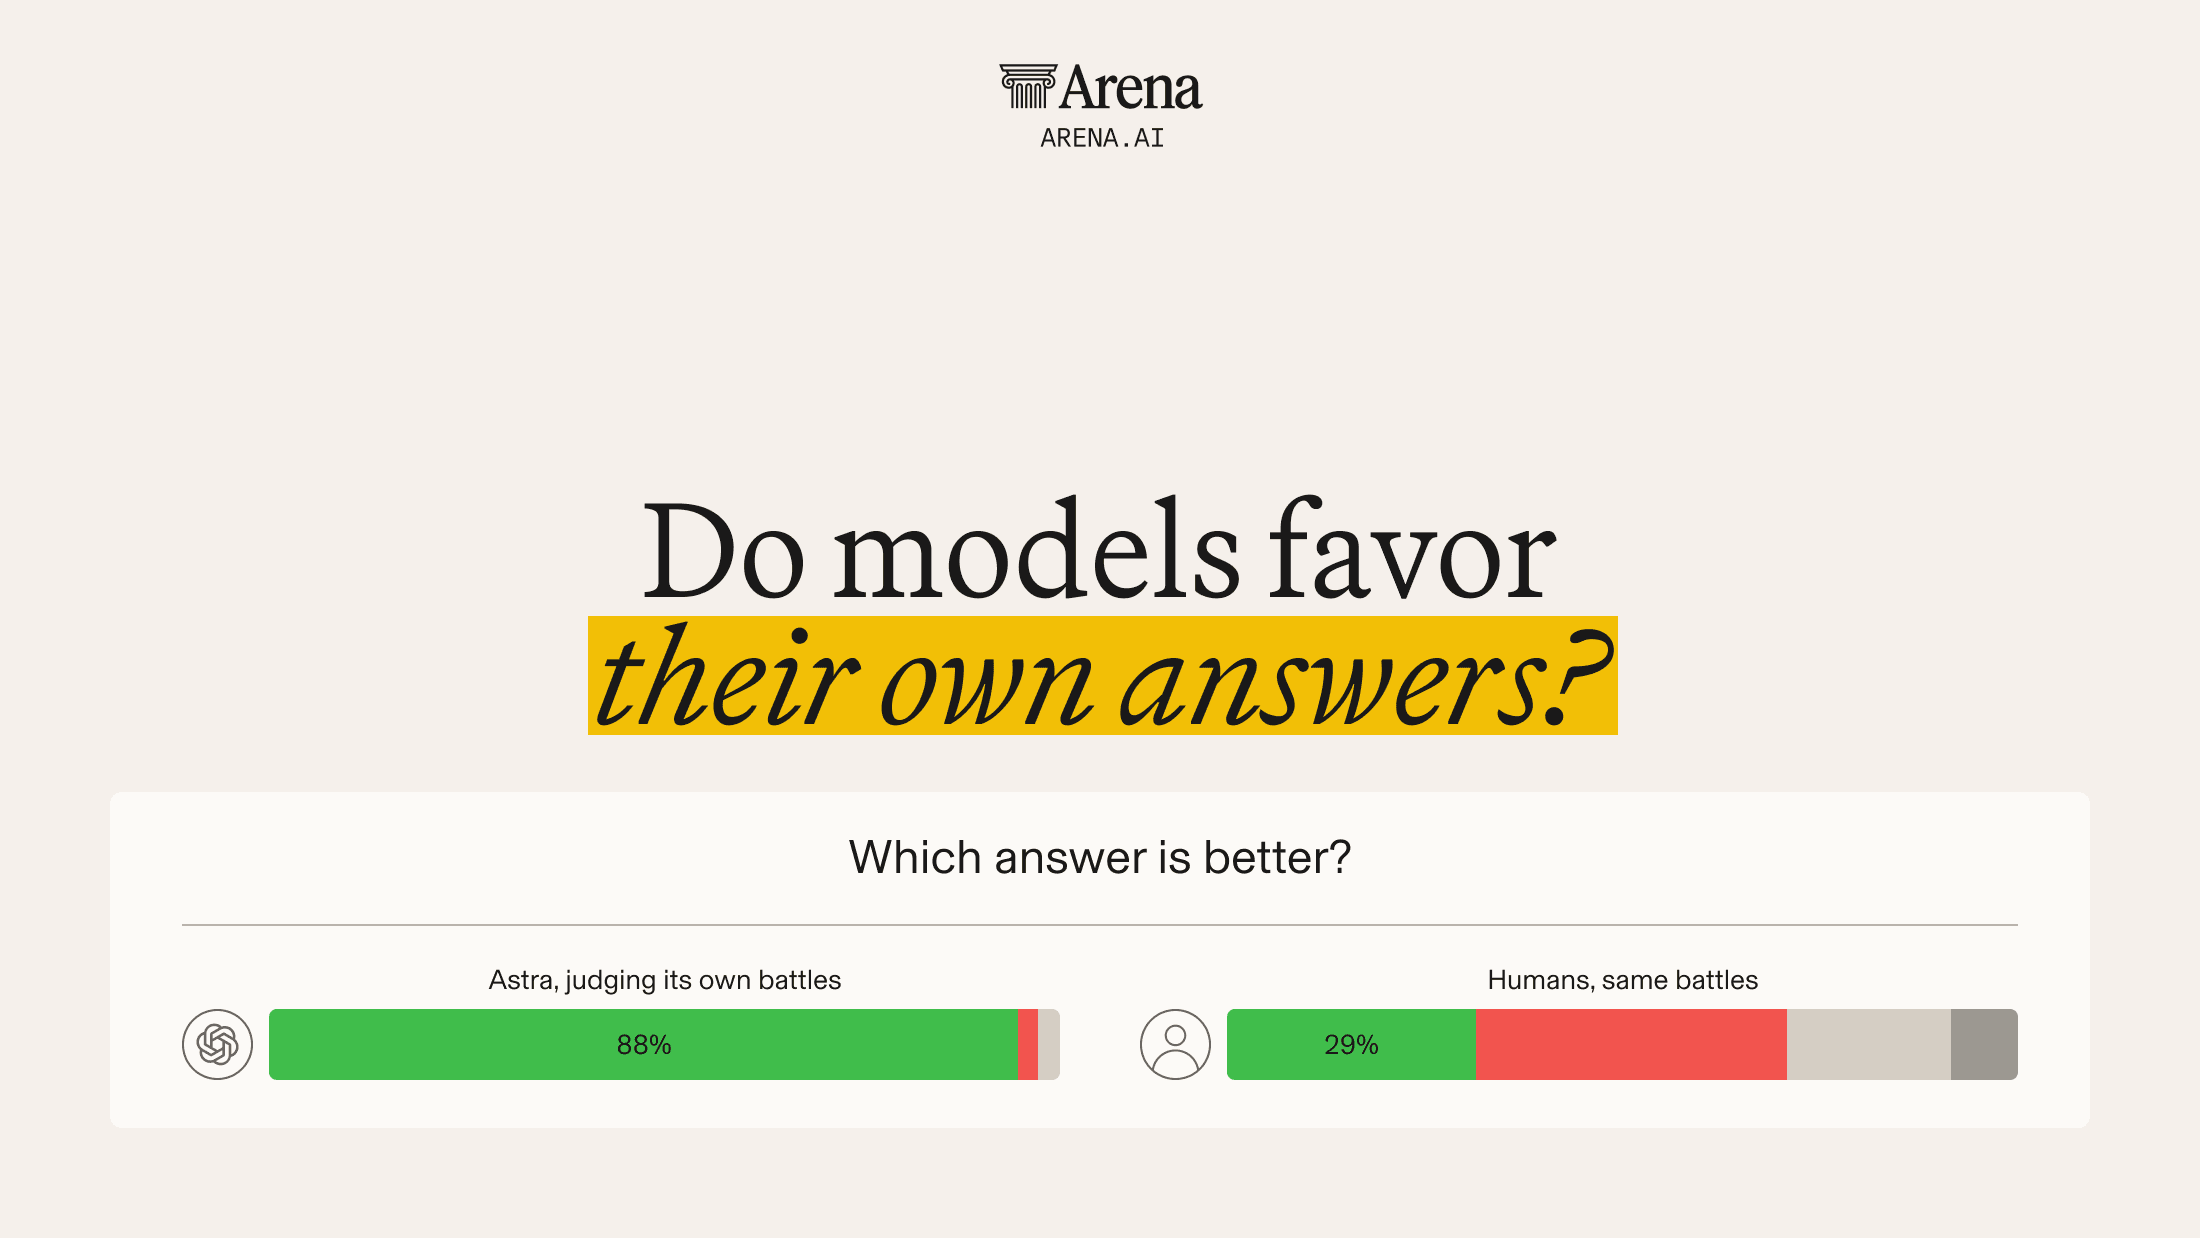
In battles where one answer was its own, Astra called its own answer better 88% of the time and picked the opponent's only 2% of the time. The people who submitted the prompts picked Astra's answer 29% of the time, the opponent's 36%, and called a tie or "both bad" in the rest. Fable rated its own answer better in 72% of battles, compared with 38% for people.
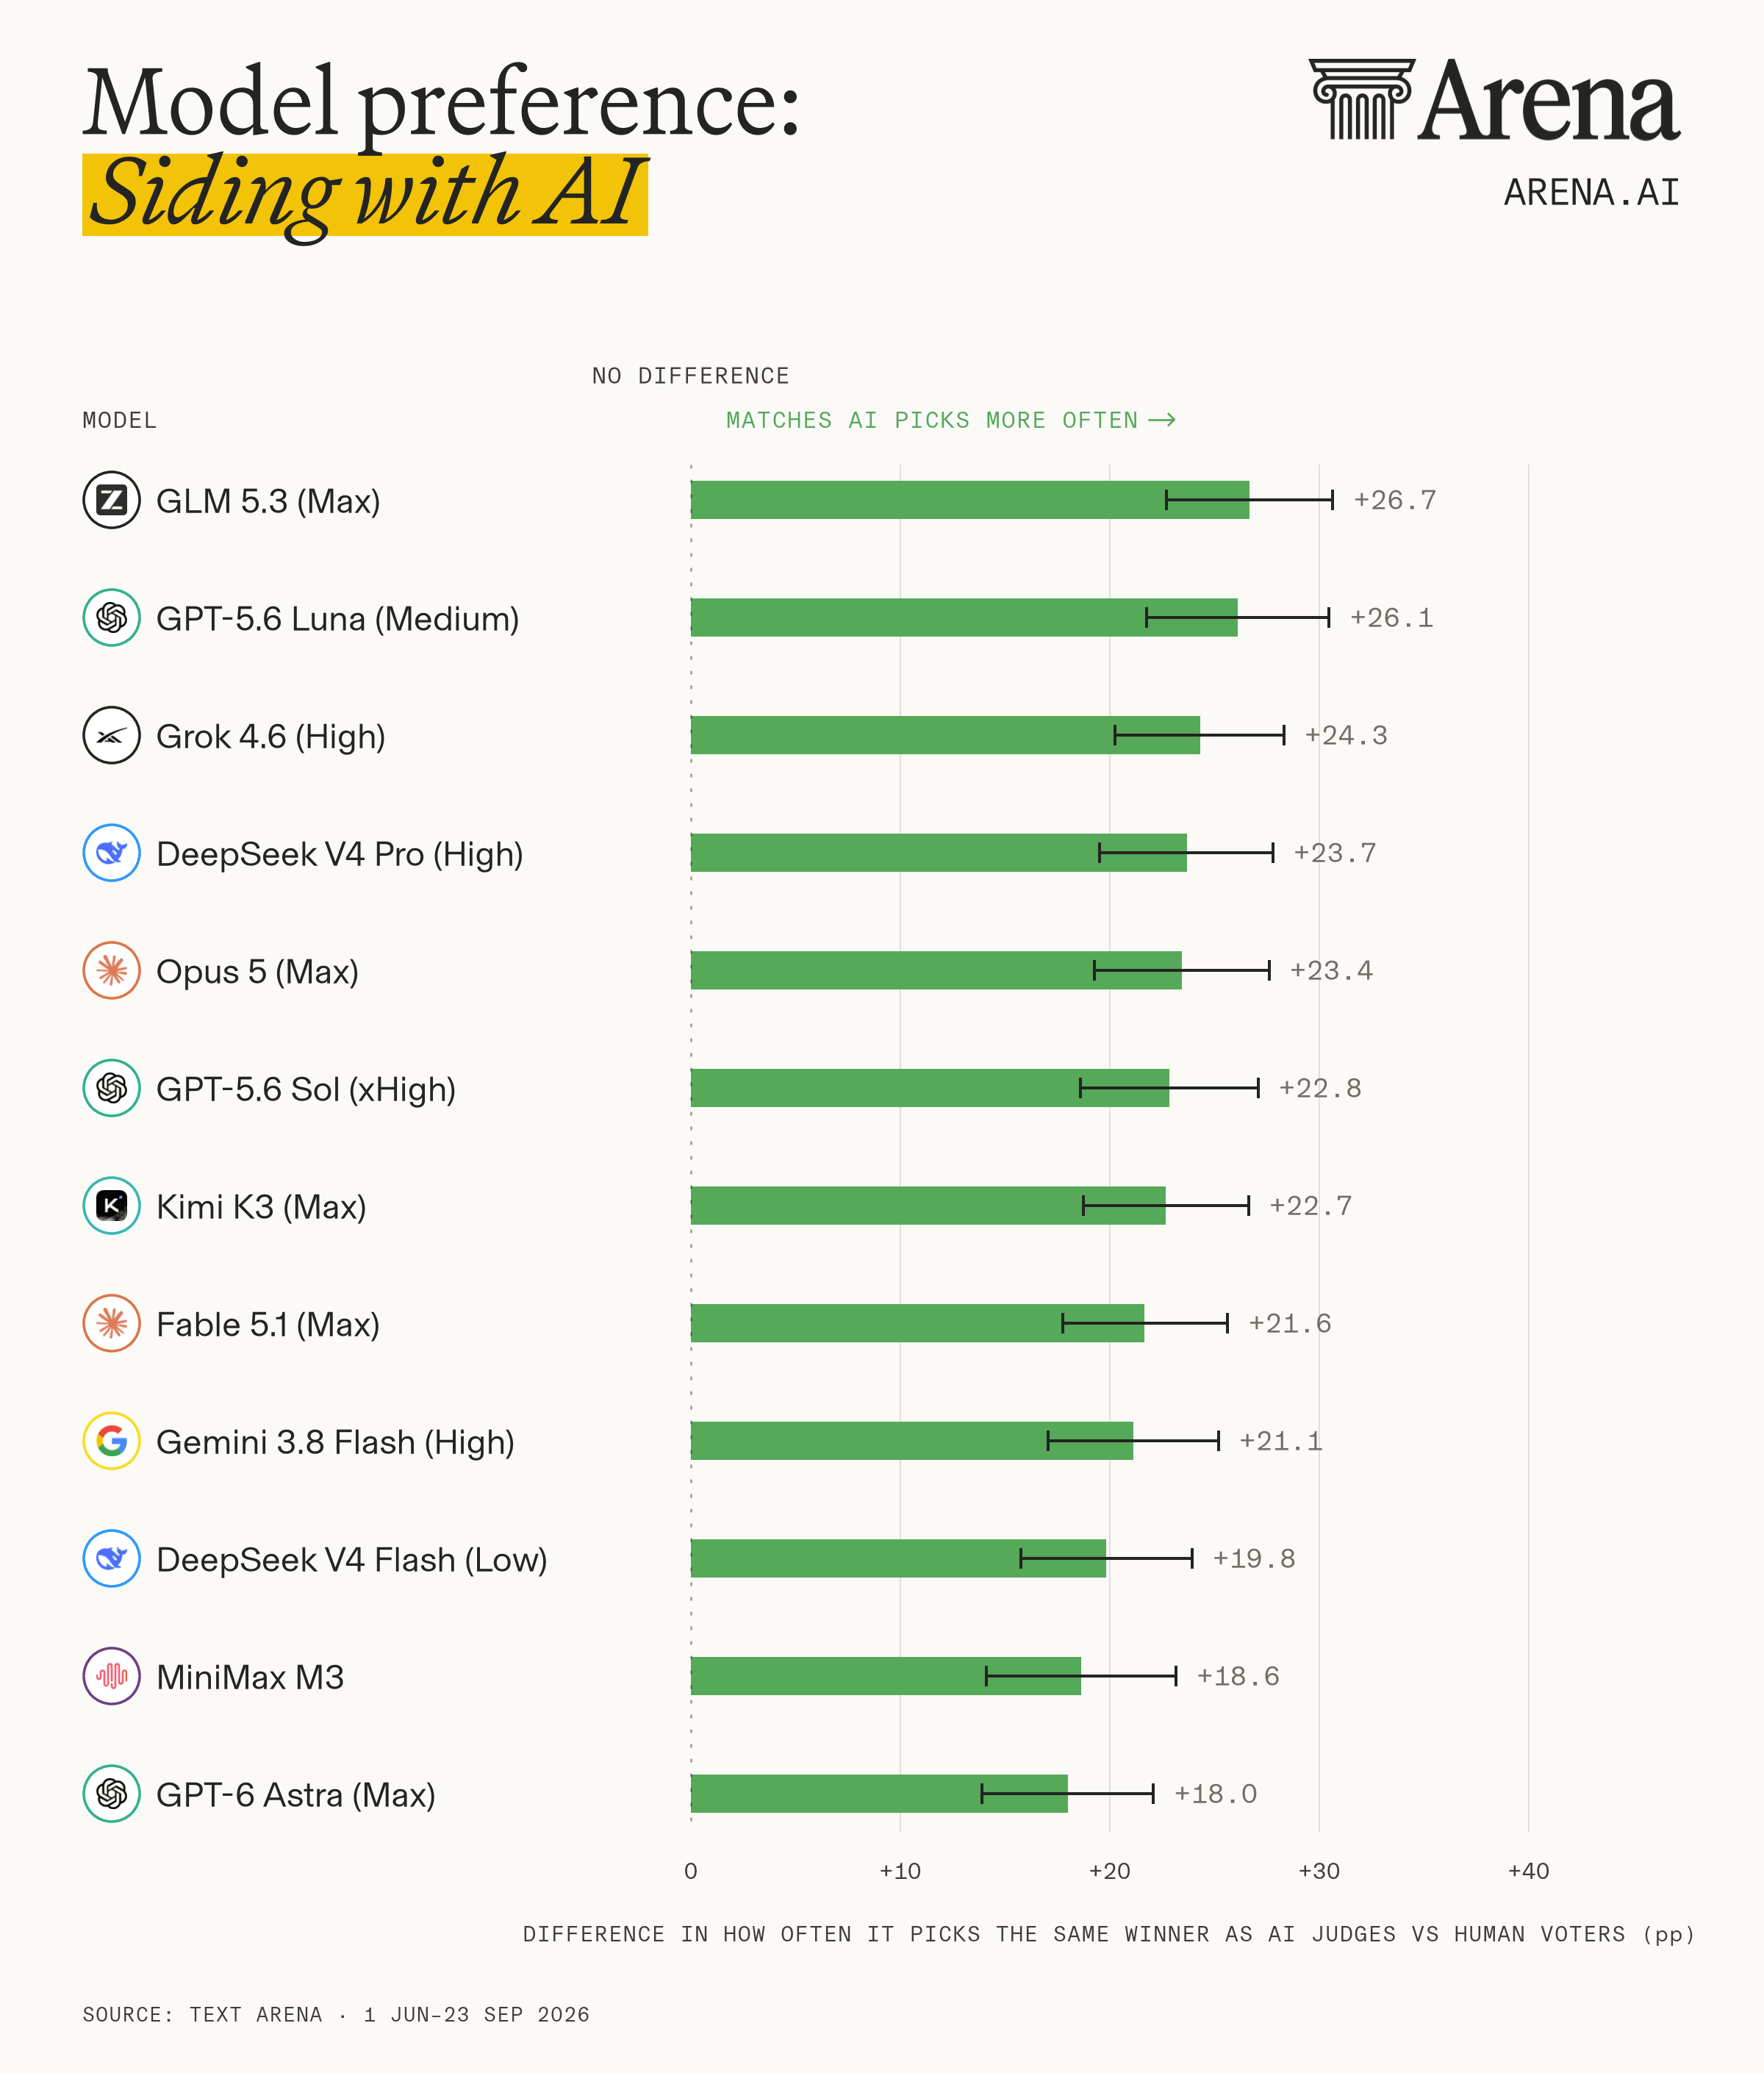
This self-preference becomes a clear pattern as we consider additional models. Across 12 LLMs, the models backed themselves about 70% more often than humans did. On average, a model picked its own answer 58% of the time, while people picked that same answer 34% of the time.
If we set ties aside, the top self-fans look even more one-sided.