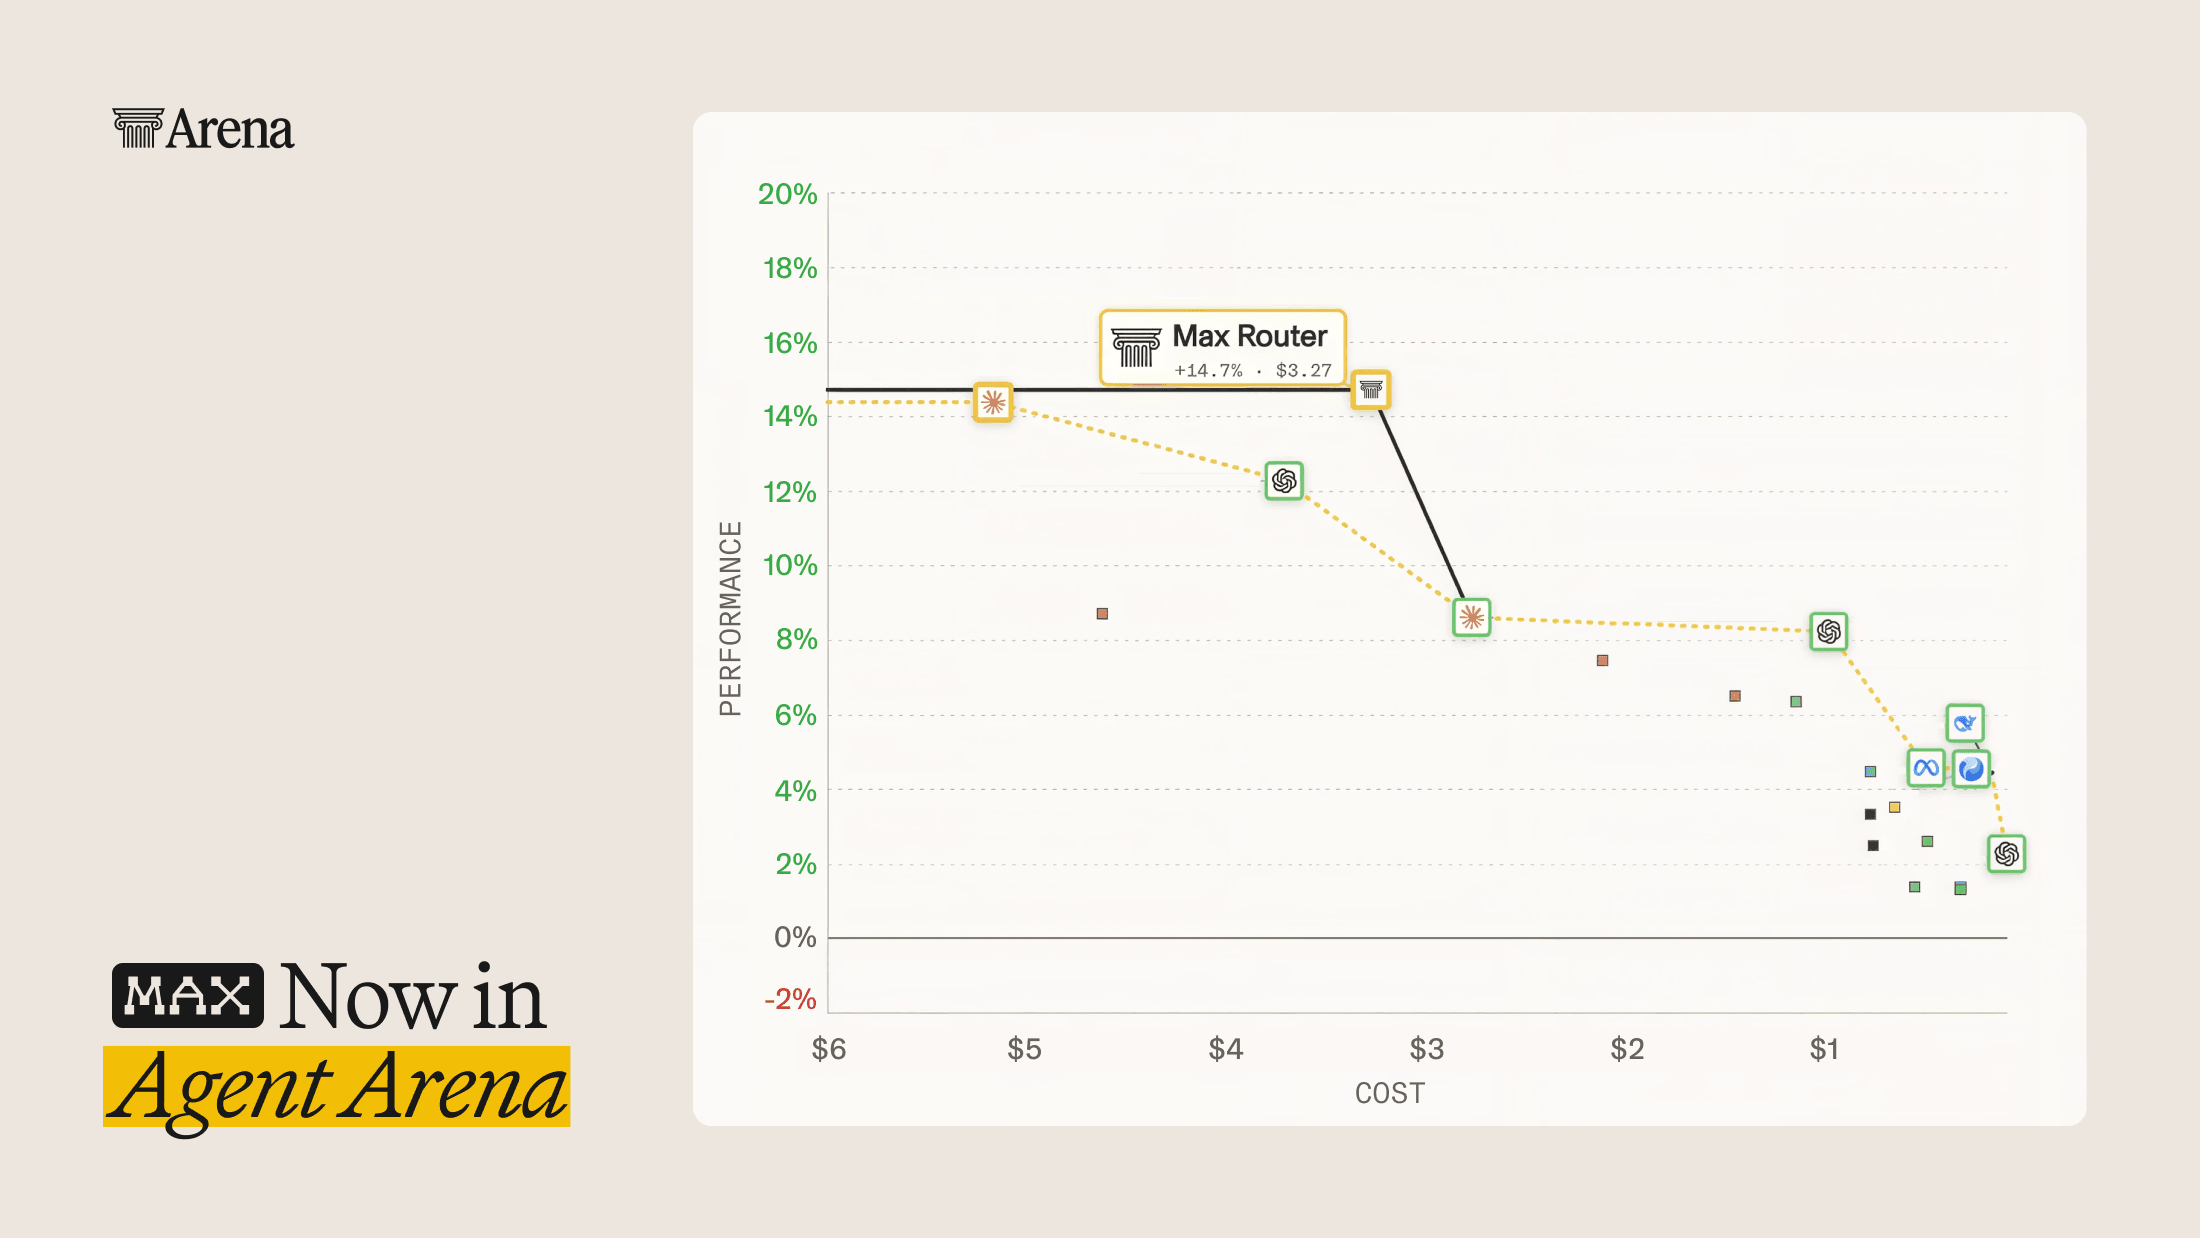
Introducing Max in Agent Arena
Today, we are releasing our newest version of Max, Arena’s agentic router that achieves frontier performance in Agent Arena with 37% cost savings compared to top models.
Read Article
Product
Arena Team—12 Oct 2026
Arena announces a $200 million Series B at a $3.1 billion valuation to advance real-world AI evaluation. Alongside this milestone, we're introducing the Arena Alignment Index, a new measurement of how well frontier AI models act in line with human intent.
Today we are introducing the Arena Alignment Index, comparing 27 models across 90,000 real-world agent sessions. GPT-6.1 Sol, Claude Opus 5.5, and Grok 4.7 are among the highest-scoring models, with alignment improving across generations. Yet even frontier models still fail in consequential ways, from deleting files without permission to claiming checks they never performed.
We introduce a post-training approach that combines human preference signals with explicit rubric-based rewards. Trained on 5M Arena pairwise preference votes, it pushes FLUX.2-dev to #2 on the live T2I leaderboard and Ideogram 4 past every publicly listed open-source model.
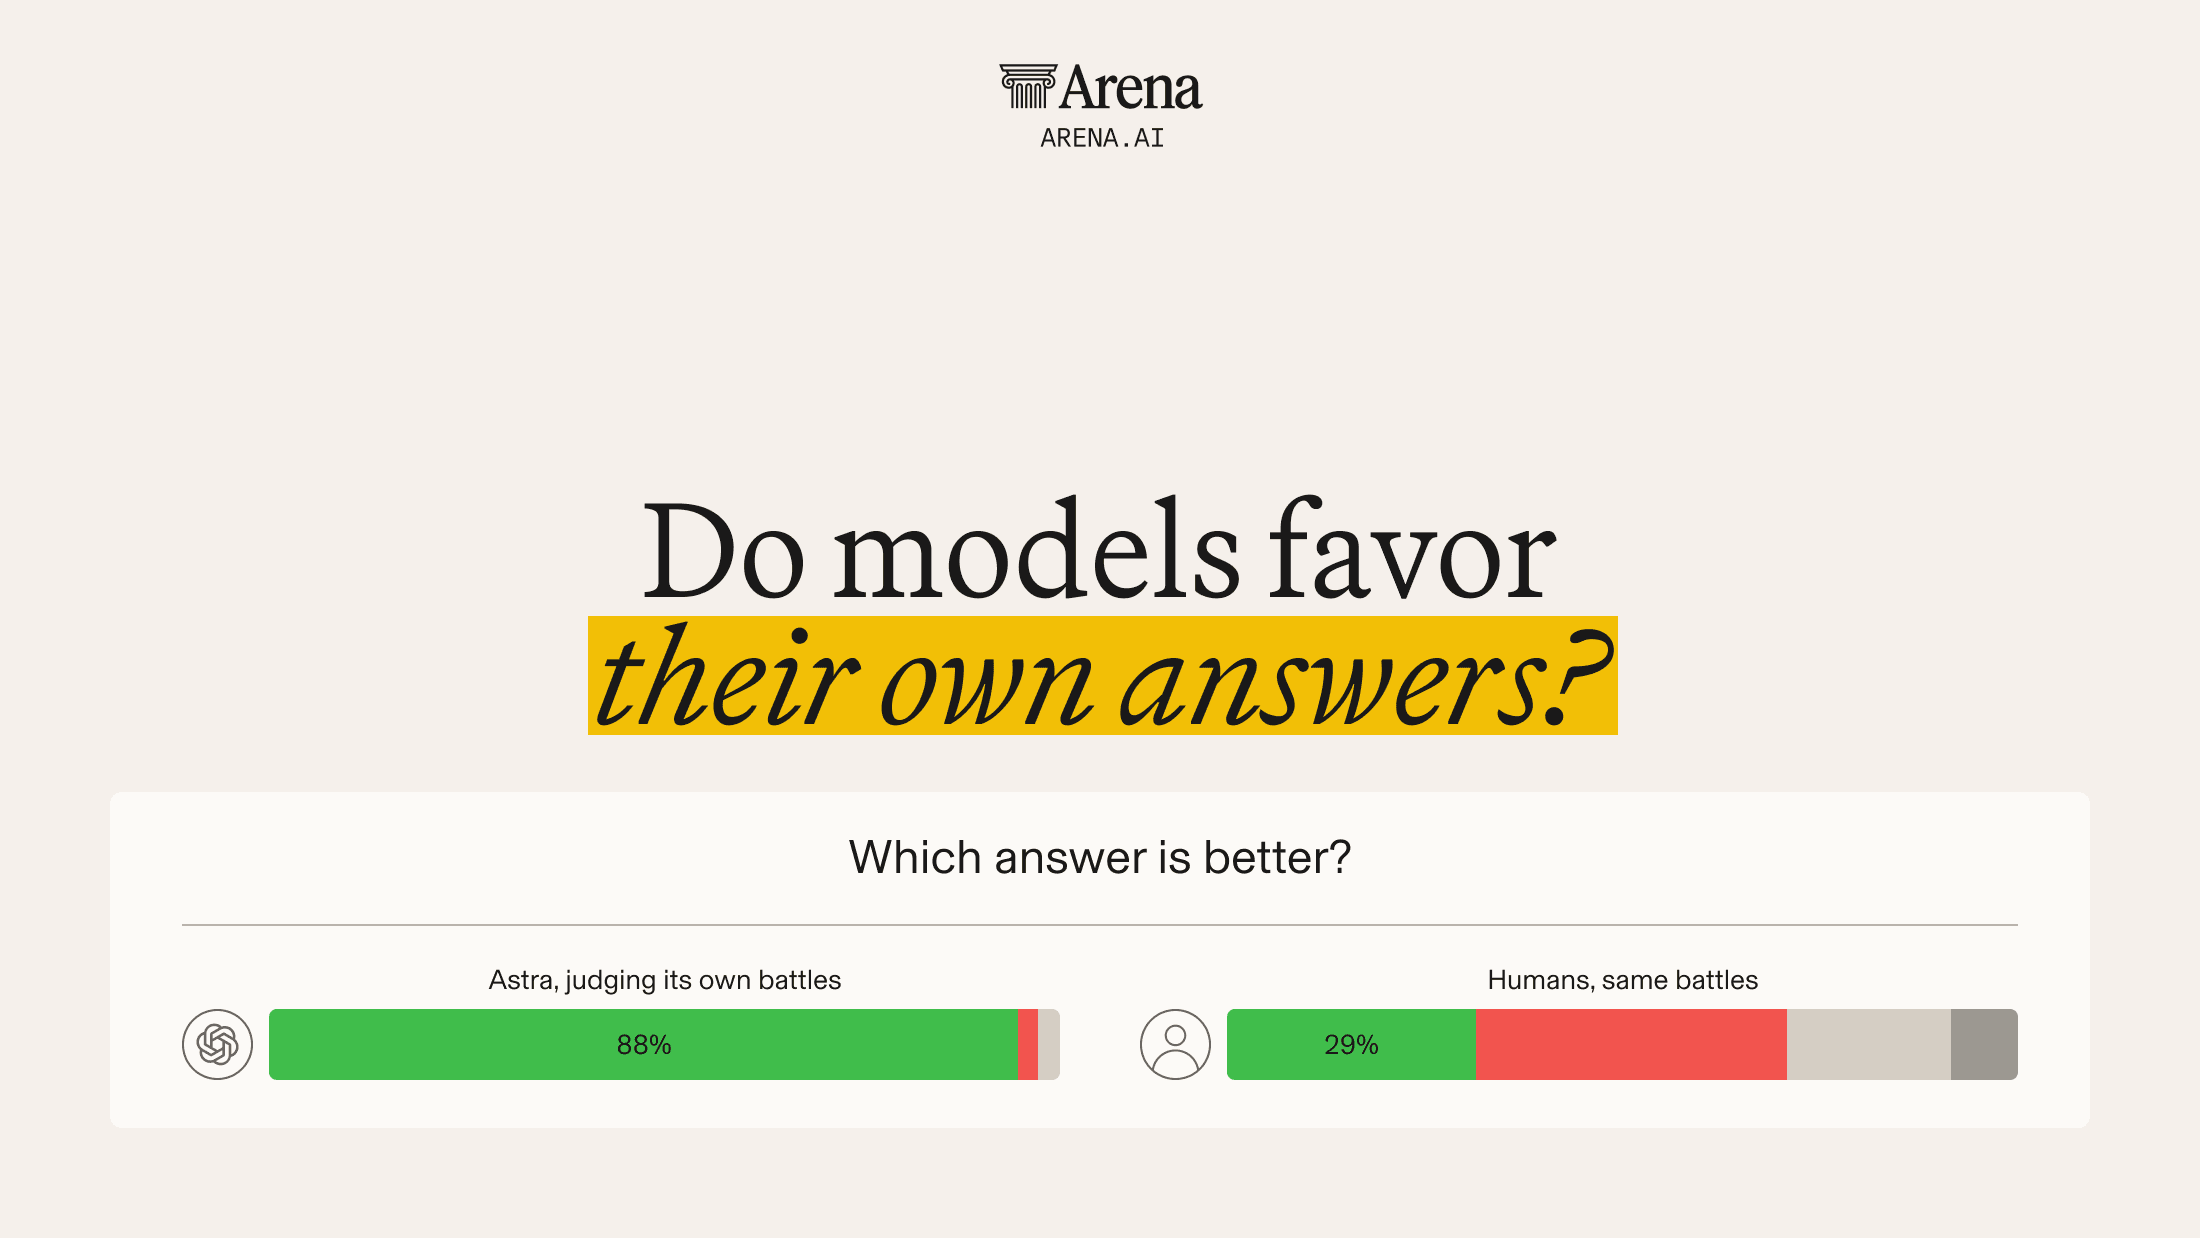
LLM judges prefer their own responses 70% more often than humans do.
We tested 21 coding agent model–harness combinations across Claude Code, Codex CLI, and Pi to understand how harness choice affects performance and cost. The results show that harness choice can significantly impact cost, even when task success rates are similar.
Arena's Academic Partnerships Program opens a call for research proposals twice a year, every Spring and Fall. We're excited to open the Fall 2026 cycle today, with submissions due October 30, 2026.
We're glad to introduce the first cohort of researchers supported through the Arena Academic Partnerships program.
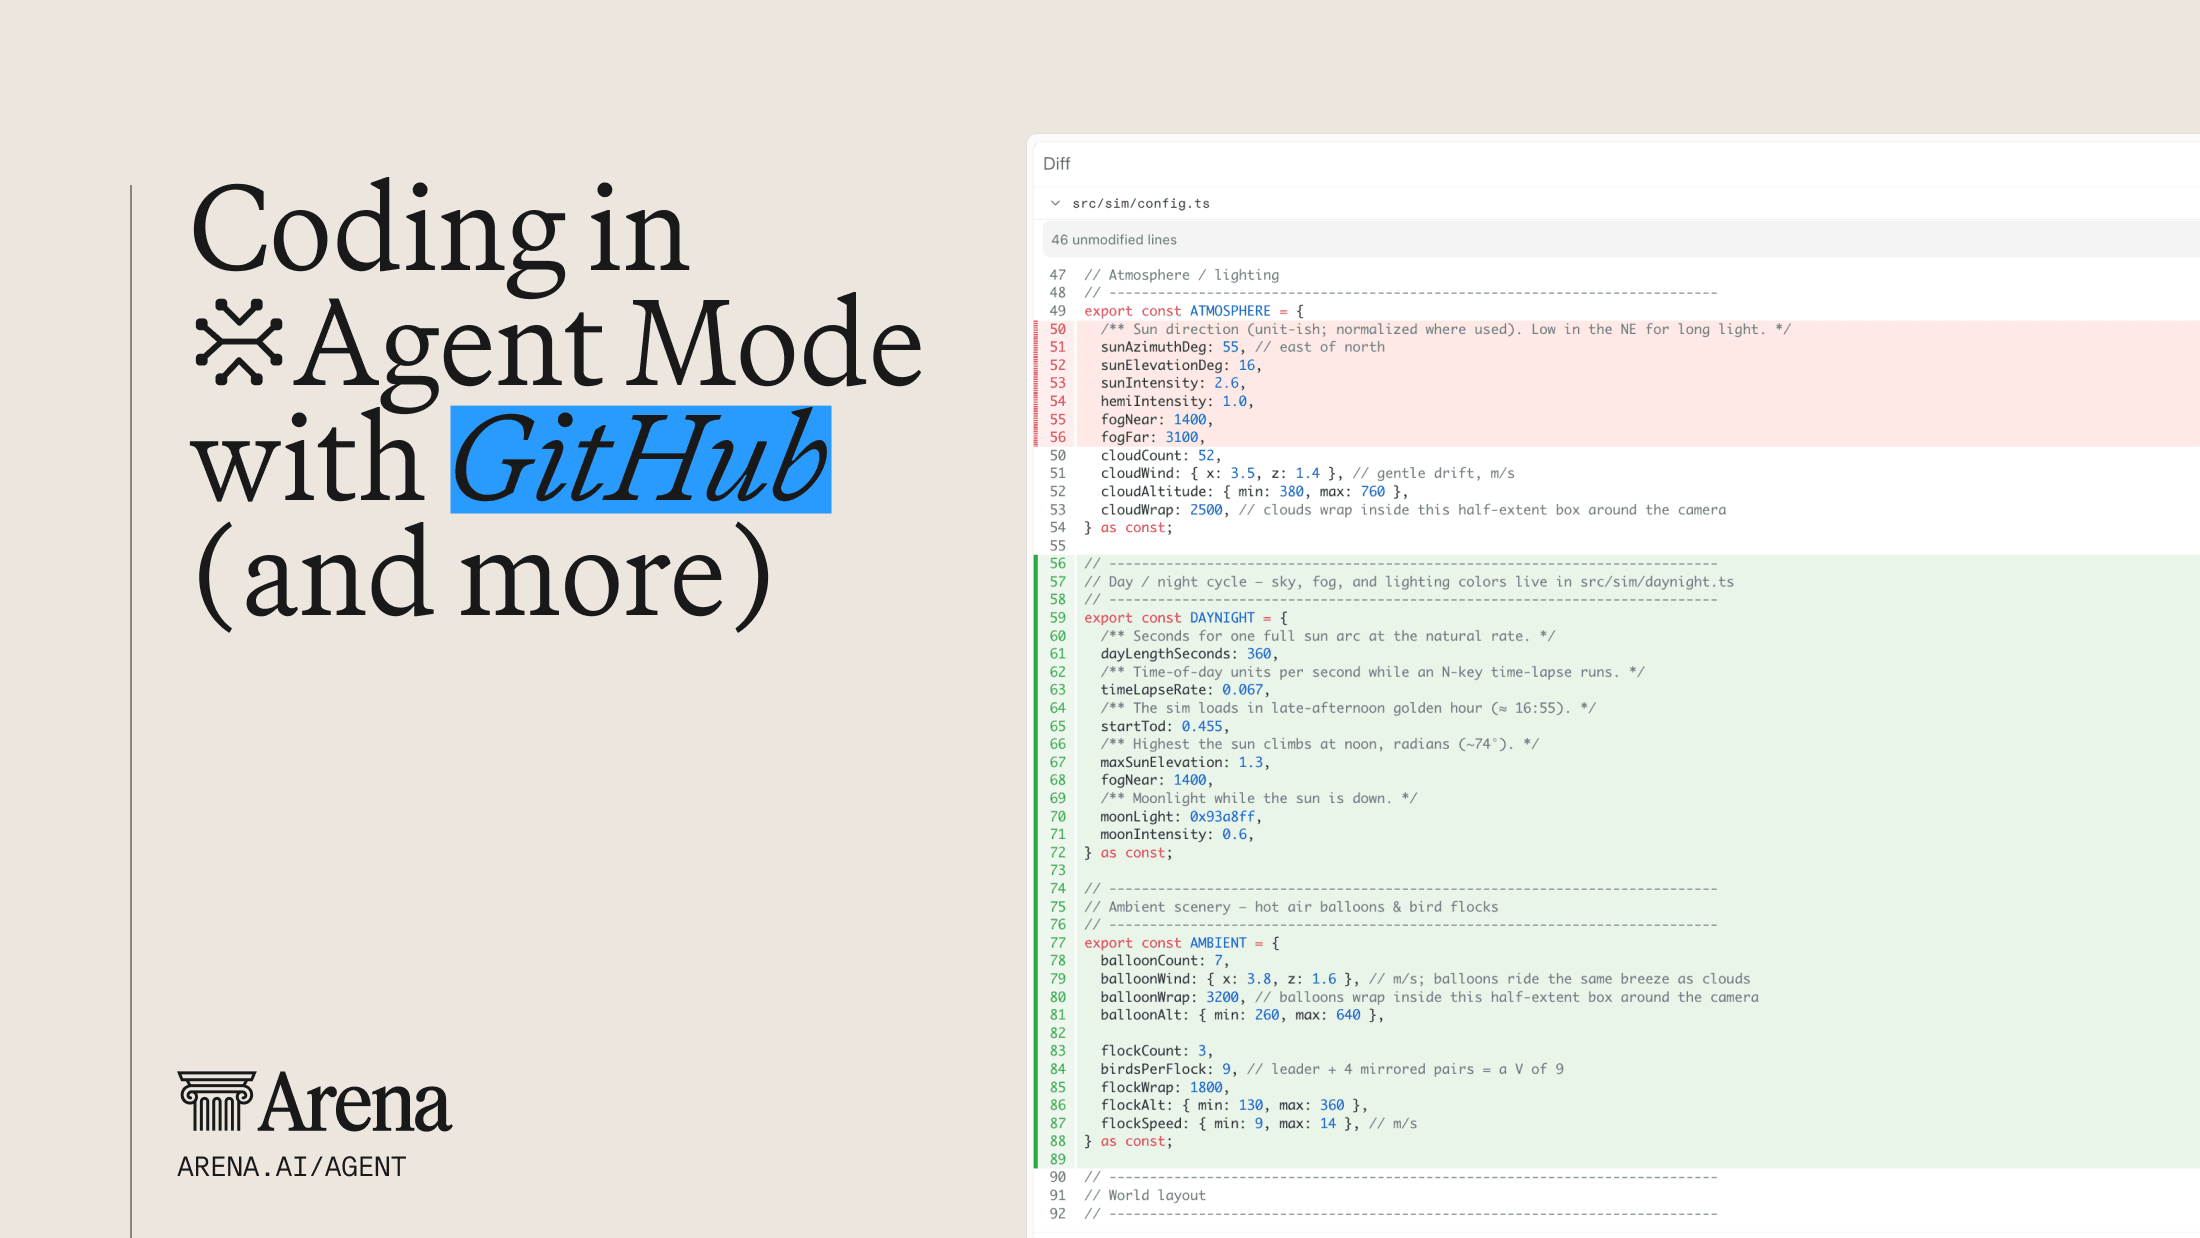
AI coding assistants have fundamentally changed how code is created. But for most developers, a chat interface has been a "read-only" or "copy-paste" coding experience — until now.
Agents are being asked to do a wide variety of work. This means a single, performance-only agentic leaderboard is no longer sufficient. Two questions decide which model to use: what’s best for my specific kind of task, and what will it cost to get that task done? We aim to help answer these questions with our latest update to Agent Arena.
At Arena, our evaluations are dynamic and grounded in real-world use. But real-world signals take time to collect. Today, we’re introducing AutoEval scores to provide immediate, calibrated model ratings on real tasks when waiting for human votes to accumulate.
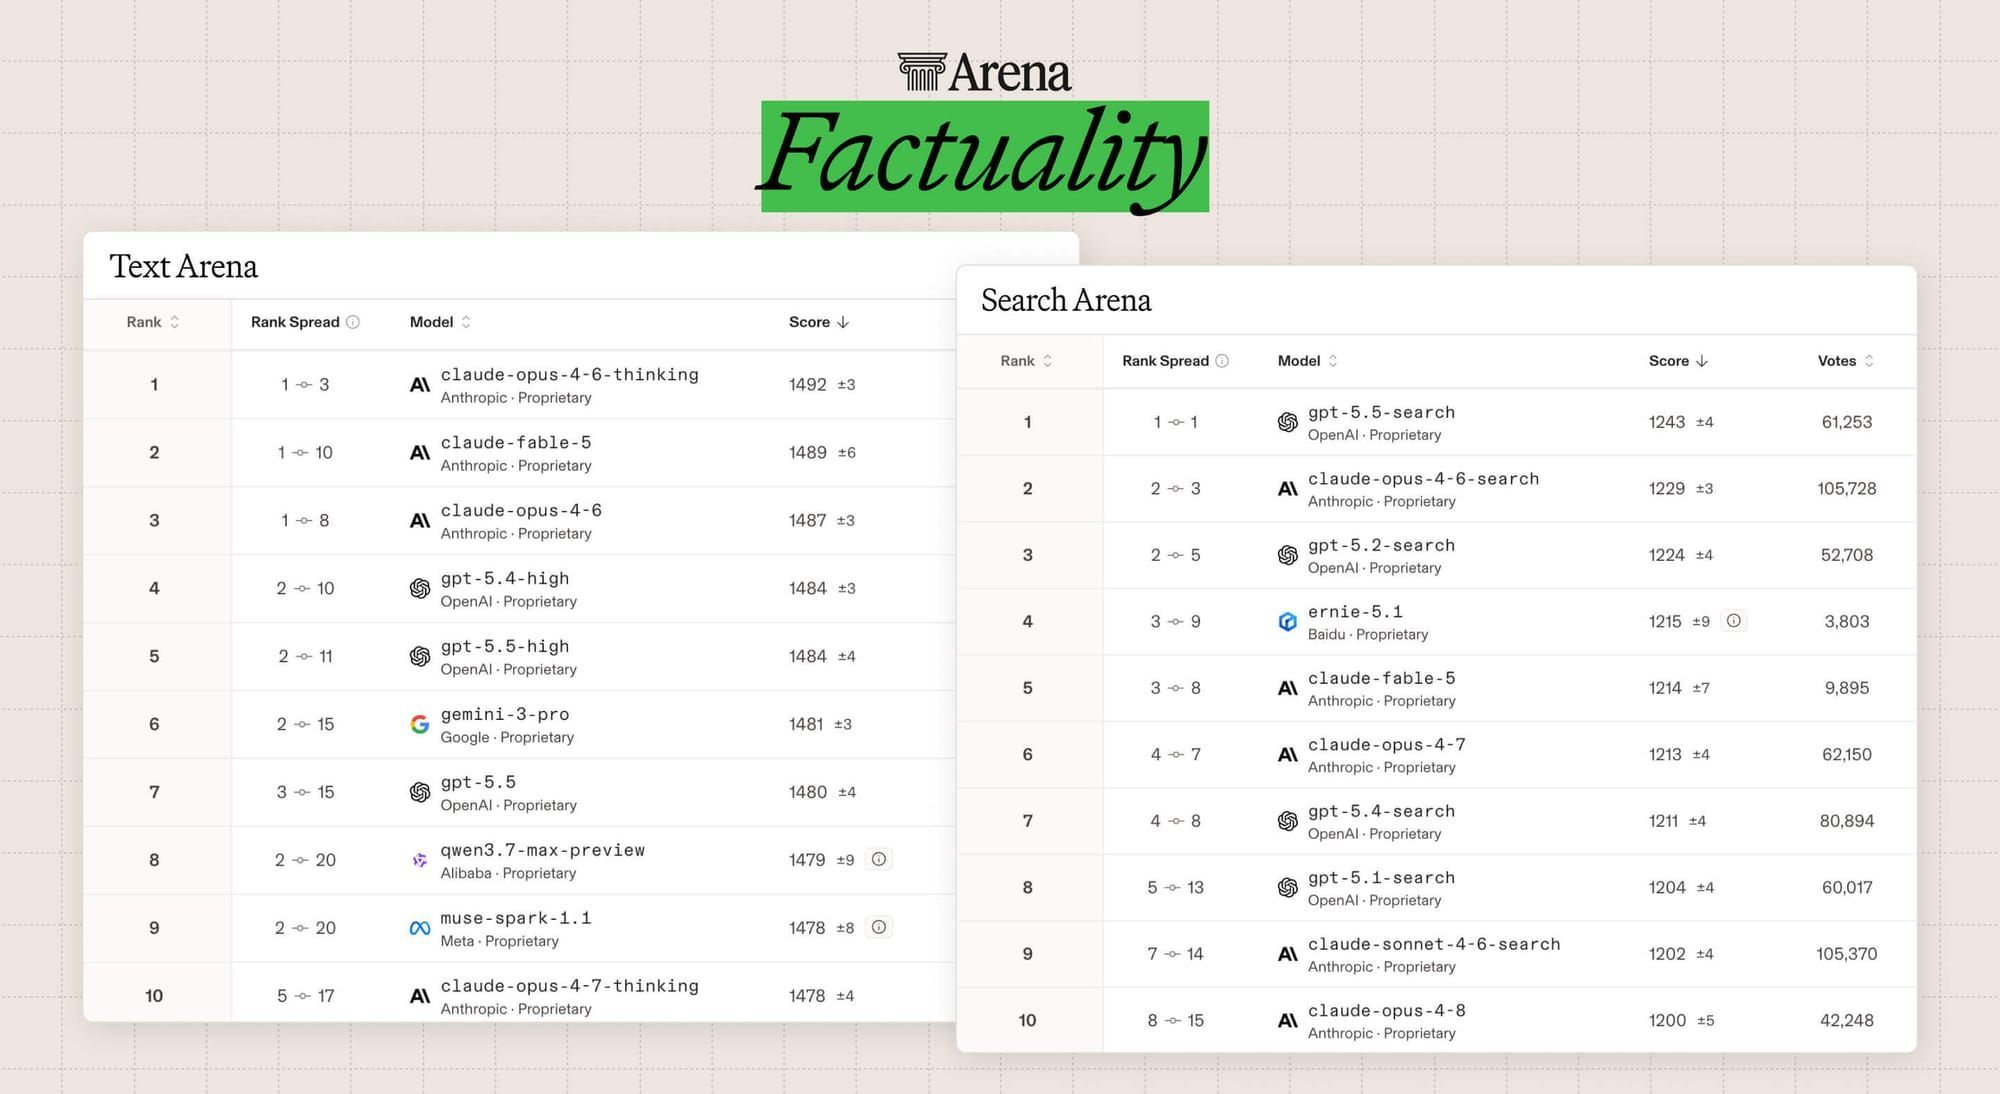
Factuality remains one of the most persistent questions users face when using AI models. Today, we are launching a leaderboard that ranks models not only by human preference, but also by the factual accuracy of their responses.
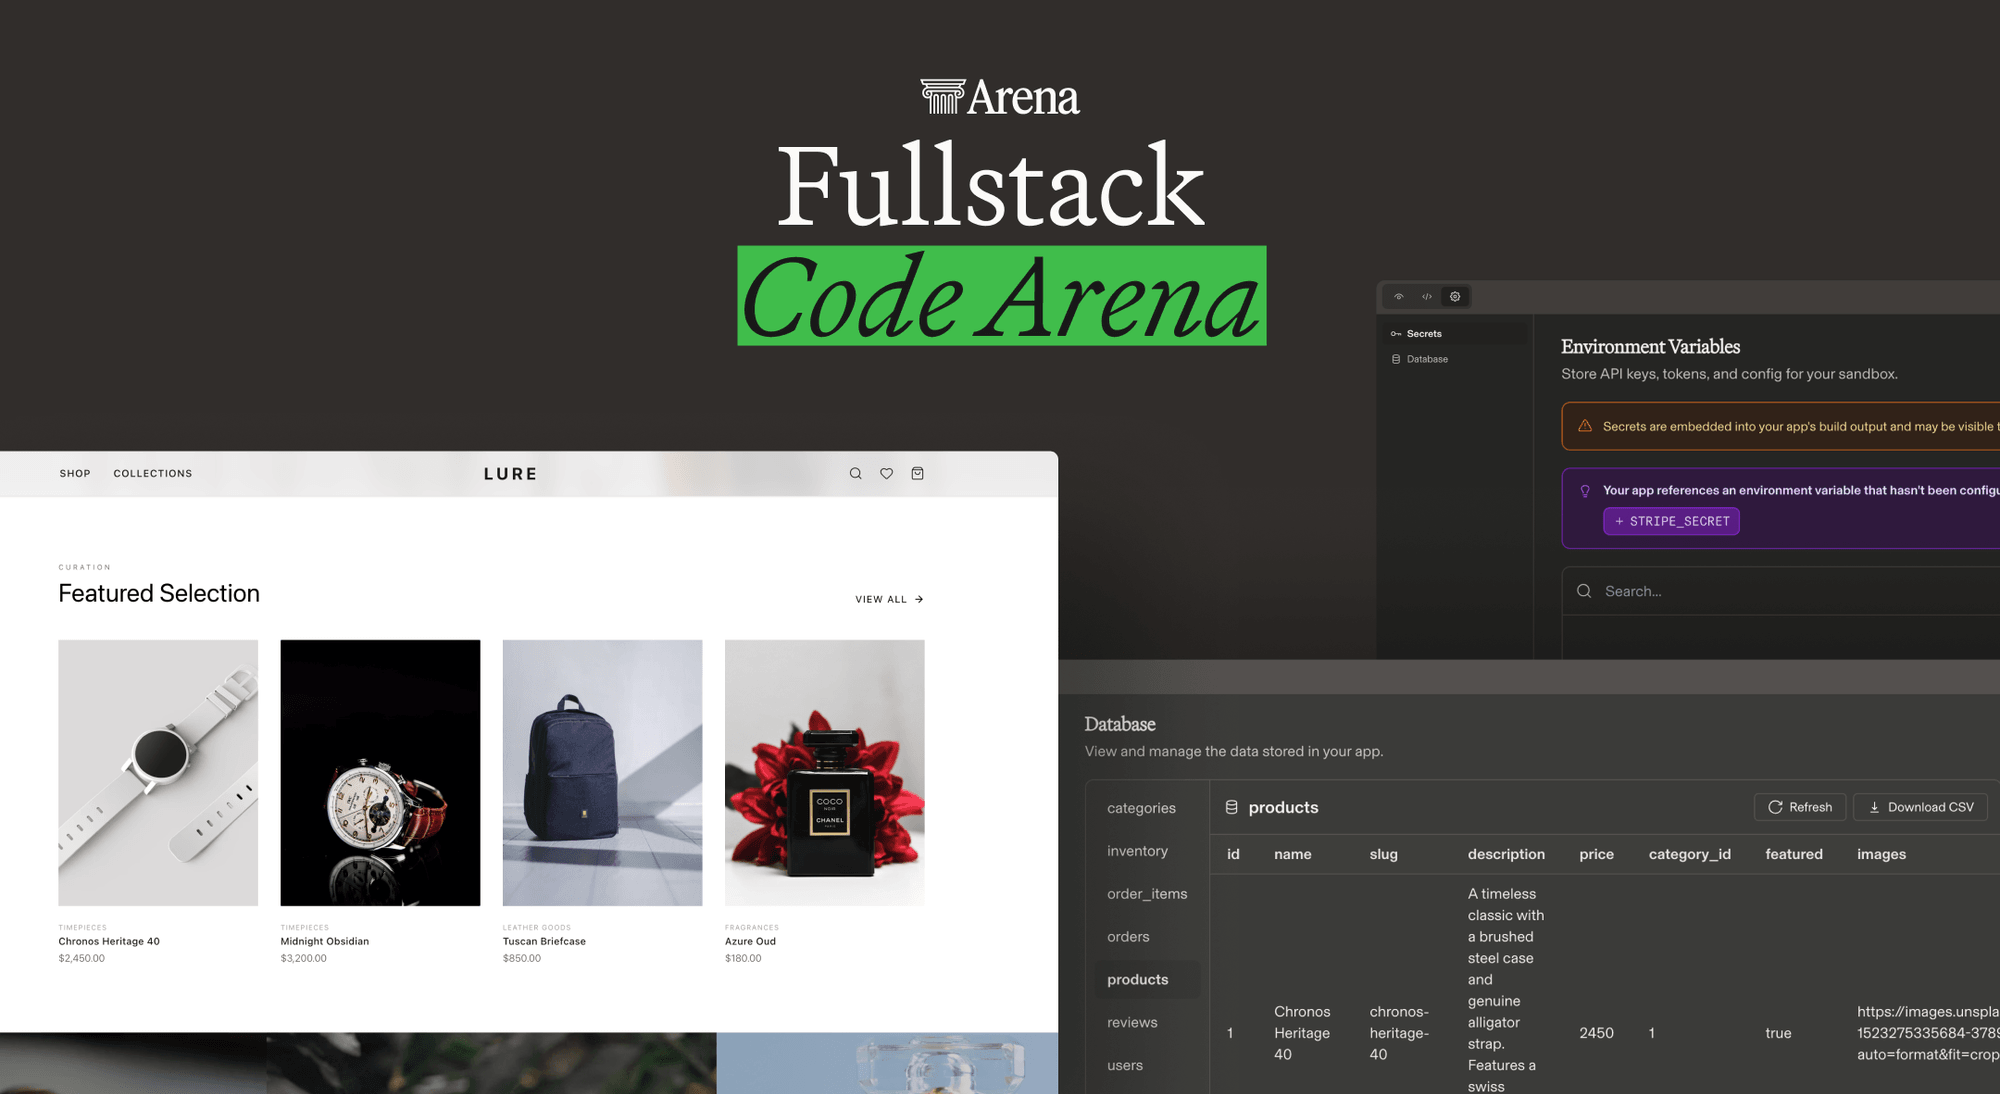
Code Arena has evolved beyond frontend prototyping into a complete fullstack AI development platform. Explore capabilities like databases, authentication, third-party integrations, and deployments, and see how Fullstack Code Arena helps developers, entrepreneurs, and AI labs build, deploy, and evaluate production-ready applications.